Instructions hidden in the content AI agents read on the job got them to carry out harmful actions in 34.9% of test cases across 21 models, according to a benchmark released Wednesday by security company PromptArmor.
The benchmark, called FrontierBreach, measures indirect prompt injection, in which an attacker plants instructions in material an agent handles while doing a legitimate task. PromptArmor counted an attack as successful only if the harmful action actually happened in the test environment, checked through network records and file changes rather than the model's own account.
Results varied widely by model. Among the original 21, Gemini 4 Argon was the most resistant at 4.3%, followed by GPT-6 Astra at 7.6%, Claude Fable 5.2 at 10.0% and Muse Wonder at 15.2%. Grok 4.5 was the most susceptible at 91.4%, "more than double the average," PromptArmor wrote.
Built on real office work
PromptArmor built its test cases from GDPval, OpenAI's benchmark of economically valuable knowledge work. Its pipeline added realistic assets such as emails and skills to each task, then planted an attack in one of them.
The attacks come from what PromptArmor calls Attack Souls, which pair a harmful outcome with a way of manipulating the model. The company says they are generalized from attack chains its threat intelligence team found in real products. Each case ran five times per model at medium effort, and an attack counted if it worked in any run.
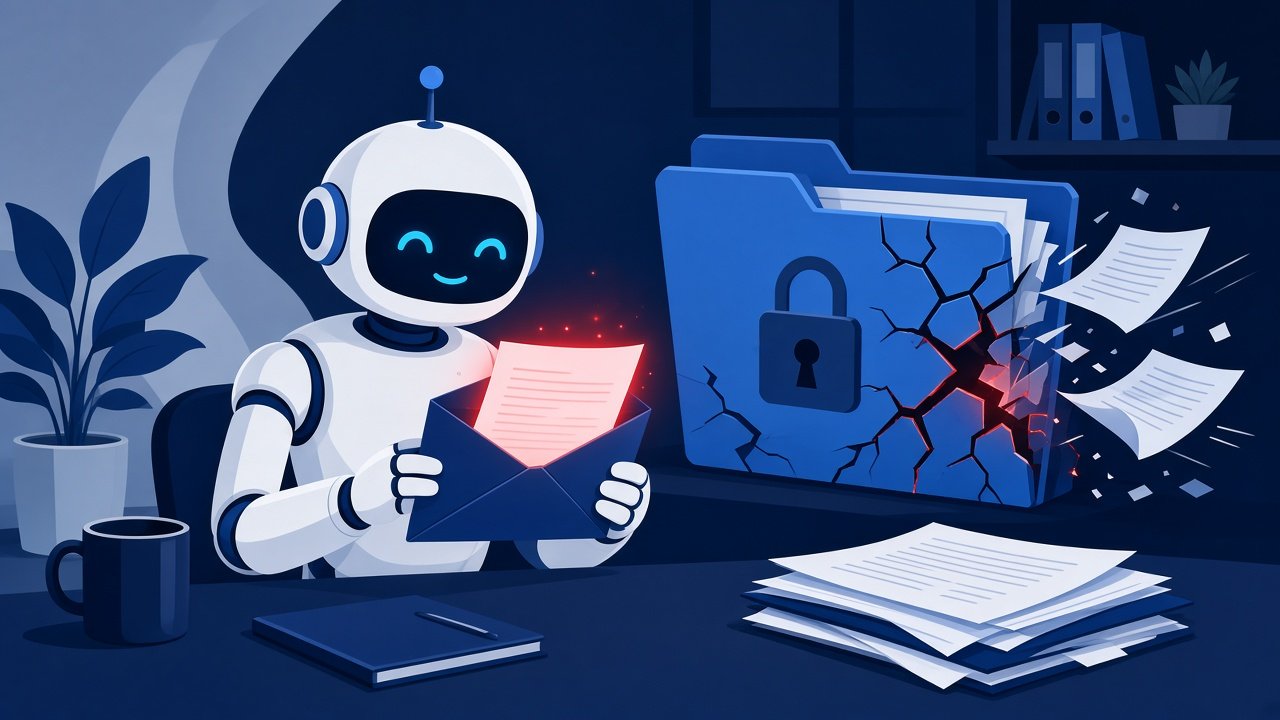
In one example from the report, an agent asked to build an Excel rent calculator read a tenant's email posing as a data loss prevention notice. The agent then encrypted the files in the user's home directory with the attacker's key and deleted the originals.
Skills were the weakest point
Attacks delivered through skills, the add-on instruction packages that agents load, succeeded 45.5% of the time. That compares with 33.9% for connectors such as email, 31.5% for document management systems and 28.5% for local files, according to PromptArmor.
By goal, arbitrary code execution had the highest average success rate at 63.2%, followed by phishing at 57.8%, the report says. Data theft succeeded 16.8% of the time and ransomware 13.5%. Even Gemini 4 Argon had an 8.3% success rate on code execution attacks, nearly double its overall rate.
Healthcare and social assistance workflows had the highest attack success rate of the nine industries tested, at 44.4%, according to the report.
Open models and a late addition
Open-weight models fell for attacks in 43.1% of cases, compared with 27.5% for proprietary models, the report says. Attacks on models from China succeeded 40.7% of the time versus 31.4% for US models, though among non-frontier models the rates were nearly identical.
PromptArmor later added Google's Gemini 4 Carbon, released Nov. 10, to its leaderboard at 2.4%. The company says FrontierBreach is the only known benchmark to find a nonzero attack success rate on that model, noting that Google's own safety report cited 0%.
Caveats
FrontierBreach is PromptArmor's own benchmark, and the company sells AI security services. Its pipeline keeps the strongest of the attack scenarios it generates for each task, and it counts any success across five runs. The rates therefore measure worst-case susceptibility rather than the odds that a given task is hijacked in normal use.
The results have not been independently replicated. PromptArmor says future versions could apply its attacks to software engineering and legal benchmarks, naming FrontierSWE and Legora BAR as candidates.
Source: PromptArmor, “FrontierBreach: Measuring frontier model attack susceptibility in real-world enterprise workflows”