OpenAI chief scientist Jakub Pachocki has called on frontier AI developers to agree on common limits on model development, measured by a metric they can track across labs, that they would commit not to cross until their ability to monitor AI behavior reaches a set milestone. He made the proposal in a post titled "Perplexity and Intelligence," published on OpenAI's website on November 22, alongside internal pretraining measurements the company had not shared before.
"Publishing our internal perplexity measurements took some consideration; it gives competitors a clearer picture of where we stand," Pachocki wrote, adding that the concern "is outweighed by the urgency of establishing shared safety measures across the industry."
The numbers
Perplexity measures how well a model predicts the next token, and lower is better. OpenAI tracks the log of perplexity, also called cross-entropy loss, on a held-out dataset drawn from its internal codebase, according to the post's footnotes.
Pachocki gave GPT-3.5 a log-perplexity of about 0.99 on that dataset and GPT-4 about 0.91. He wrote that once OpenAI's models reached losses below 0.8, the company saw new capabilities emerge in cybersecurity and mathematics, and that it was "not at all clear a priori" those abilities would appear at those thresholds.
He said that after OpenAI upgraded to a model with a log-perplexity of about 0.76, it began producing major results on open problems in mathematics that the company had been posing to its models for more than a year. The post does not name that model.
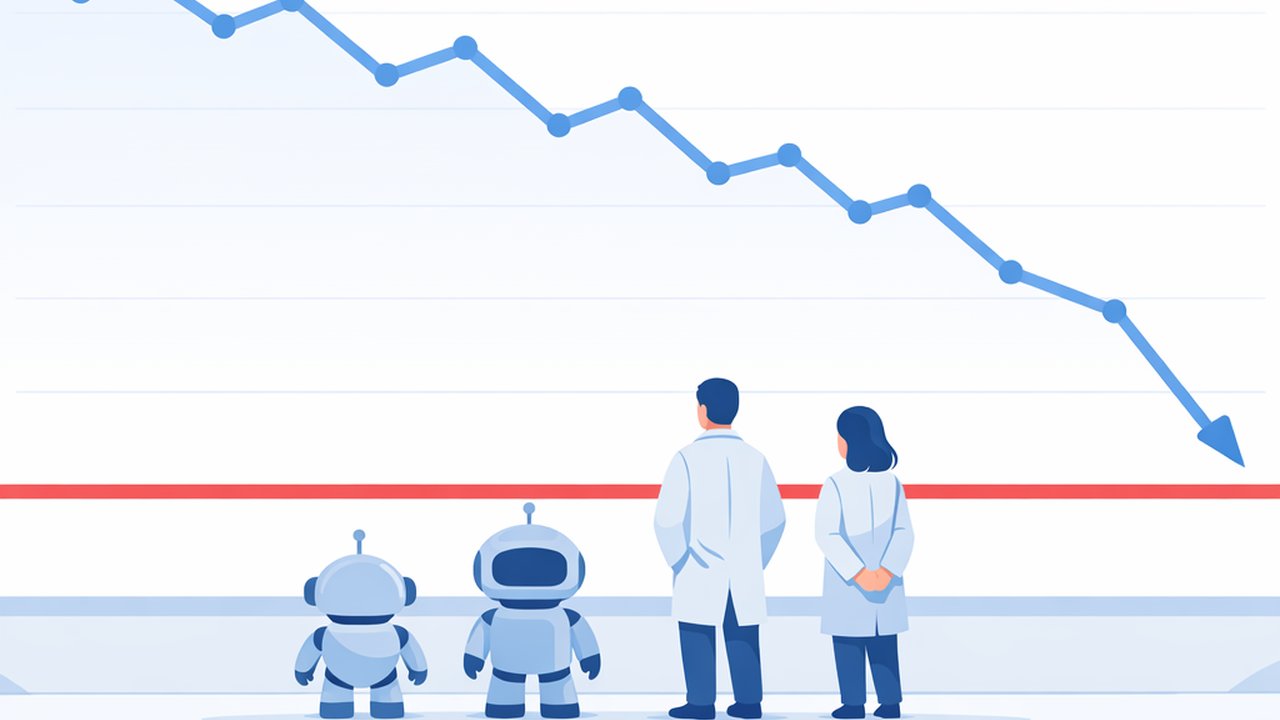
Pachocki wrote that a chart of OpenAI's losses shows a steep acceleration in 2026. He attributed it mostly to long-term research and compute investments and "only in a smaller part to automation," though he wrote that recent models have already received "meaningful design contributions coming from AI."
AI doing AI research
The proposal rests on a warning about AI agents working on their own development. Pachocki wrote that discussion usually centers on full recursive self-improvement, a state he said should be avoided "for the sake of maintaining human control." He argued that a step change could come earlier, from AI taking part in algorithmic research on pretraining alone.
"As soon as 2027 we could conceivably see a similar avalanche of fundamental pretraining advancements," he wrote, comparing it to the run of math results. He said AI will also help with alignment and monitoring, but that this progress "is unlikely to be fast enough to allow the full potential acceleration in pretraining."
Extrapolating from recent progress, he wrote, labs should expect major new capabilities in a log-perplexity window of about 0.68 to 0.7, along with "further degradation" of current alignment auditing methods and more evaluation and training awareness in models.
The proposal
Pachocki wrote that frontier developers should jointly set norms for evaluating and red-teaming such models by the time they are first used, including shared transparency standards. On top of that, he called for an industry standard that names "a first limit on development" and the concrete milestone labs would need to reach before going past it. He gave a successor to chain-of-thought monitors as one example.
He acknowledged problems with perplexity as a shared yardstick. Labs use different evaluation datasets and data mixtures, which makes comparison hard, and the score does not map directly to tasks people care about. He also noted that chain-of-thought reasoning raises capabilities without lowering perplexity, and that nobody knows the metric's floor.
OpenAI CEO Sam Altman wrote on X that it was "the most important thing OpenAI has published in awhile," adding that common limits "would be very wise and help ensure safety and control." The post does not say whether any other lab has agreed to the proposal.
Source: OpenAI, Jakub Pachocki, “Perplexity and Intelligence”
Additional sources: Jakub Pachocki on X, Jakub Pachocki, “Announcement post”; Sam Altman on X, Sam Altman, “Post on Perplexity and Intelligence”